Google Ads makes it easy to change a bid strategy, expand matching, enable automation or replace creative. It is much harder to know whether the change caused a better business result. A campaign experiment can create a cleaner comparison, but only when the control, treatment, measurement and decision rule are designed before the test starts.
For US business owners, the practical goal is not to run more experiments. It is to reduce expensive guesswork while protecting lead quality, revenue measurement and day-to-day campaign stability.
Choose the right experiment type
Google’s current Experiments page includes custom experiments, Performance Max experiments, Demand Gen experiments, video experiments and other test formats. They do not all work the same way.
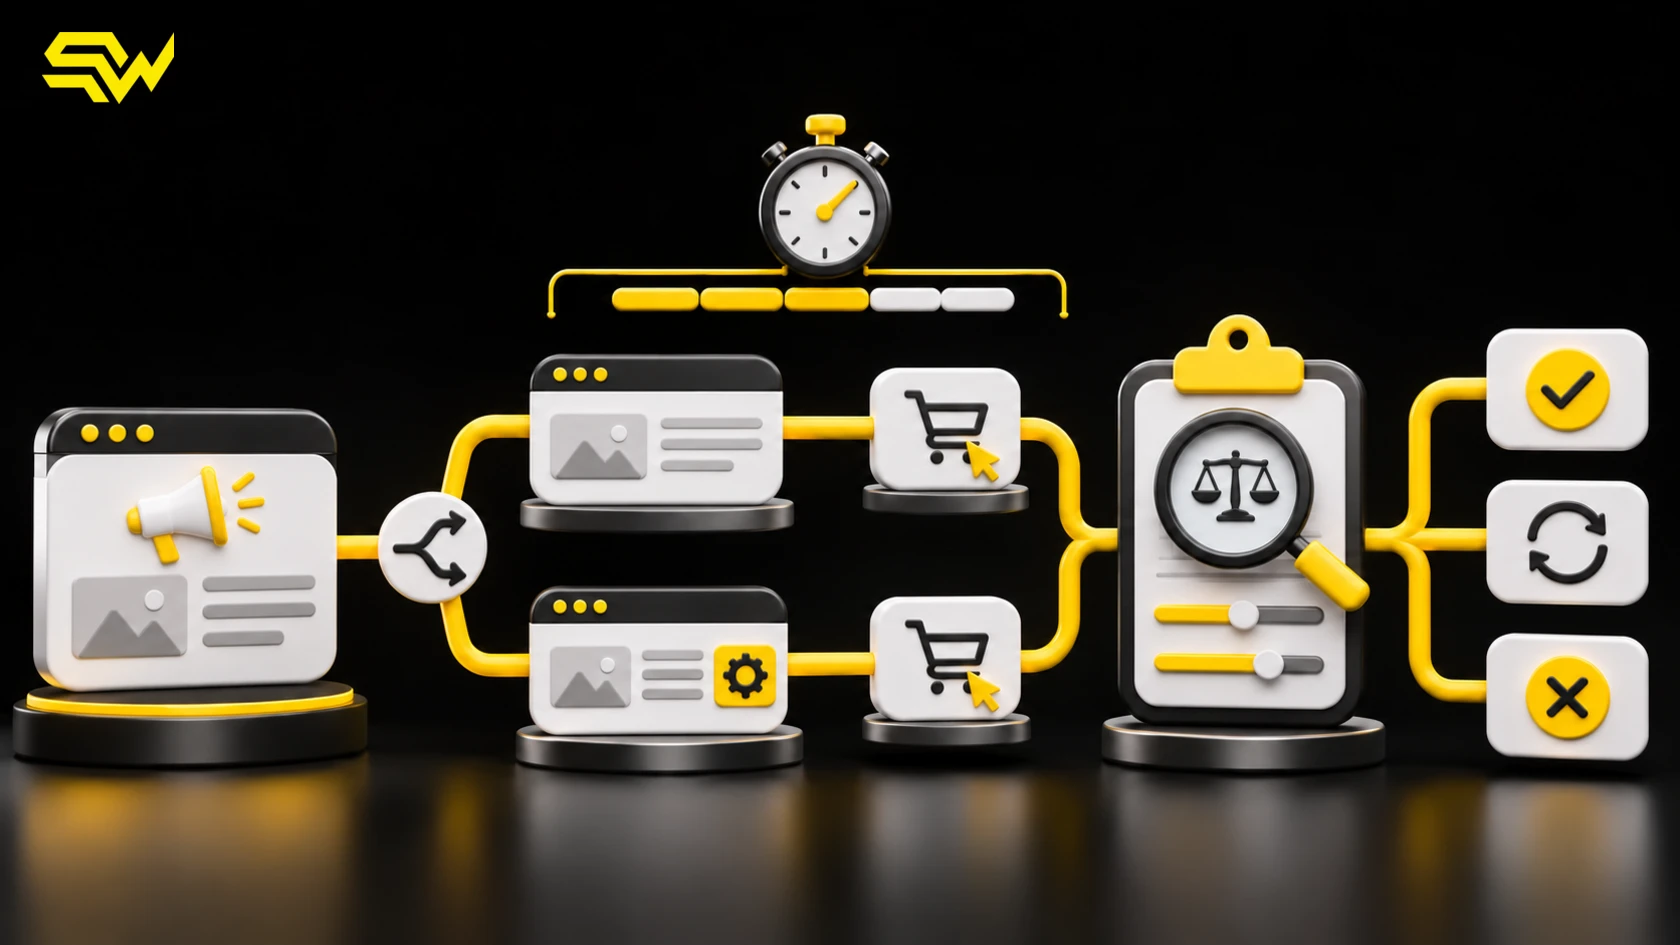
Google says custom experiments are available for Search, Display, Video and Hotel campaigns. A custom experiment creates a treatment version that shares traffic or budget with the original campaign. Search experiments can use cookie-based or search-based splits. Performance Max uses dedicated experiment formats, including uplift, upgrade and optimization experiments, rather than the standard custom-experiment path.
Evidence: what the platform can compare
Google’s Performance Max experiment documentation describes several distinct questions. An uplift experiment evaluates adding Performance Max alongside comparable campaigns. An upgrade experiment simulates shifting budget from an eligible campaign type. An optimization experiment tests a specific Performance Max feature or setting.
Recommendation: write the decision question first
Do not begin with “Let’s test Performance Max” or “Let’s test broad match.” Write a question that names the population, treatment, outcome and time frame:
For non-brand commercial searches in our active service regions, does broad match with the same conversion goals and bidding strategy produce more qualified leads at an acceptable cost than the current keyword setup?
That question is more useful than “Which campaign wins?” because it defines what stays constant and what evidence matters.
Isolate one meaningful variable
An experiment becomes difficult to interpret when the treatment changes bidding, keywords, ads, landing pages and conversion actions together. A stronger design changes one major factor while keeping the offer, geography, schedule, conversion goals and commercial constraints aligned.
Useful test variables may include:
- Broad match versus the current Search keyword approach
- One bid strategy versus another
- Final URL expansion on versus off in an eligible Performance Max test
- A new asset group or creative treatment
- A landing page variation with the same campaign settings
If the real concern is irrelevant traffic, audit the search terms and negative keywords before starting. A test should not carry avoidable structural waste into both arms.
Protect the control and treatment
Google warns that changes to the original campaign are not automatically reflected in a custom experiment. Editing either arm while the test is running can make the result harder to interpret. The base campaign must also remain active for the experiment to serve.
Before launch, record:
- Campaigns included in each arm
- Budget or traffic allocation
- Bidding settings and targets
- Conversion actions and attribution settings
- Audiences, locations, schedules and exclusions
- Ads, assets, URLs and feed scope
- Start date, planned end date and known promotions
Then establish change control. Emergency fixes—such as a broken landing page, incorrect price or policy problem—should still happen, but document the time, affected arm and likely impact. Routine optimizations can wait until the test concludes.
Use business outcomes as success metrics
Clicks and conversion volume may move while lead quality or profit deteriorates. Select a primary success metric before launch and add guardrails that reflect how the business makes money.
For a service business, the primary metric might be cost per qualified lead, with guardrails for sales-accepted rate and spend. For an eCommerce campaign, it might be conversion value relative to cost, with guardrails for gross margin, stock and return behavior. The platform may not contain every commercial outcome, so CRM and finance checks may be needed outside the experiment report.
If campaigns optimize toward form fills but the sales team evaluates qualified opportunities, first review enhanced conversions for leads. Experiments cannot compensate for an unreliable conversion definition.
Give the test enough power and time
Google’s experiment monitoring guide shows the estimated difference between treatment and control, a confidence interval and whether a result is statistically significant. Google notes that an undecided result can reflect insufficient duration, low traffic, a small split or a change too subtle to detect.
Google commonly recommends allowing experiments to run for at least four to six weeks when results remain unavailable or undecided. That is platform guidance, not a universal minimum. A high-volume campaign may accumulate useful evidence sooner, while a low-volume B2B campaign may remain inconclusive for much longer.
Plan around conversion lag, sales cycles, weekdays, promotions and seasonality. Avoid launching immediately before a pricing change, major holiday, inventory disruption or website migration. A 50/50 split often produces evidence faster, but the appropriate allocation depends on risk, budget and test type.
Read confidence without declaring certainty
A statistically significant platform result suggests the measured difference is less likely to be random under the experiment’s assumptions. It does not guarantee the treatment will keep performing after rollout. A confidence interval that includes both meaningful gain and meaningful loss is a warning that the decision remains uncertain.
Also check:
- Whether spend and auction exposure were reasonably balanced
- Whether one arm was budget constrained
- Whether conversion lag is fully represented
- Whether the result depends on brand traffic or a few large orders
- Whether lead quality changed after the recorded conversion
- Whether comparable campaigns in a Performance Max uplift test were appropriate
Google allows experiment summaries and auto-application in some workflows, but an automated “winner” should not replace a commercial review.
Decide: apply, continue or stop
Create the decision rule before viewing the result. For example:
- Apply: the primary metric improves, guardrails remain acceptable and the result is sufficiently reliable.
- Continue: the direction is promising, but the interval is wide or delayed outcomes are incomplete.
- Stop: the treatment harms the primary metric, violates a guardrail or introduces operational risk.
- Inconclusive: preserve the learning, do not label either arm a winner, and redesign only if the decision is valuable enough to justify another test.
When a Performance Max test is relevant to lead generation, use the Performance Max lead-quality audit to check goals, CRM feedback, URL controls and channel reporting before scaling.
The practical takeaway is simple: test one decision, keep the arms comparable, measure a real business outcome and accept that “no clear winner” is a valid result.
SW SOFTTECH’s Google Ads management service can help design experiments, validate conversion tracking and translate campaign results into practical next steps without promising a particular outcome. Use the free marketing action-plan builder to receive three priority improvements, recommended channels and practical next steps, plus a free consultation. To discuss a Google Ads experiment audit for your business, contact SW SOFTTECH.